Article
Gluesync Live Lab: Let's Play with Data, build your first pipeline live
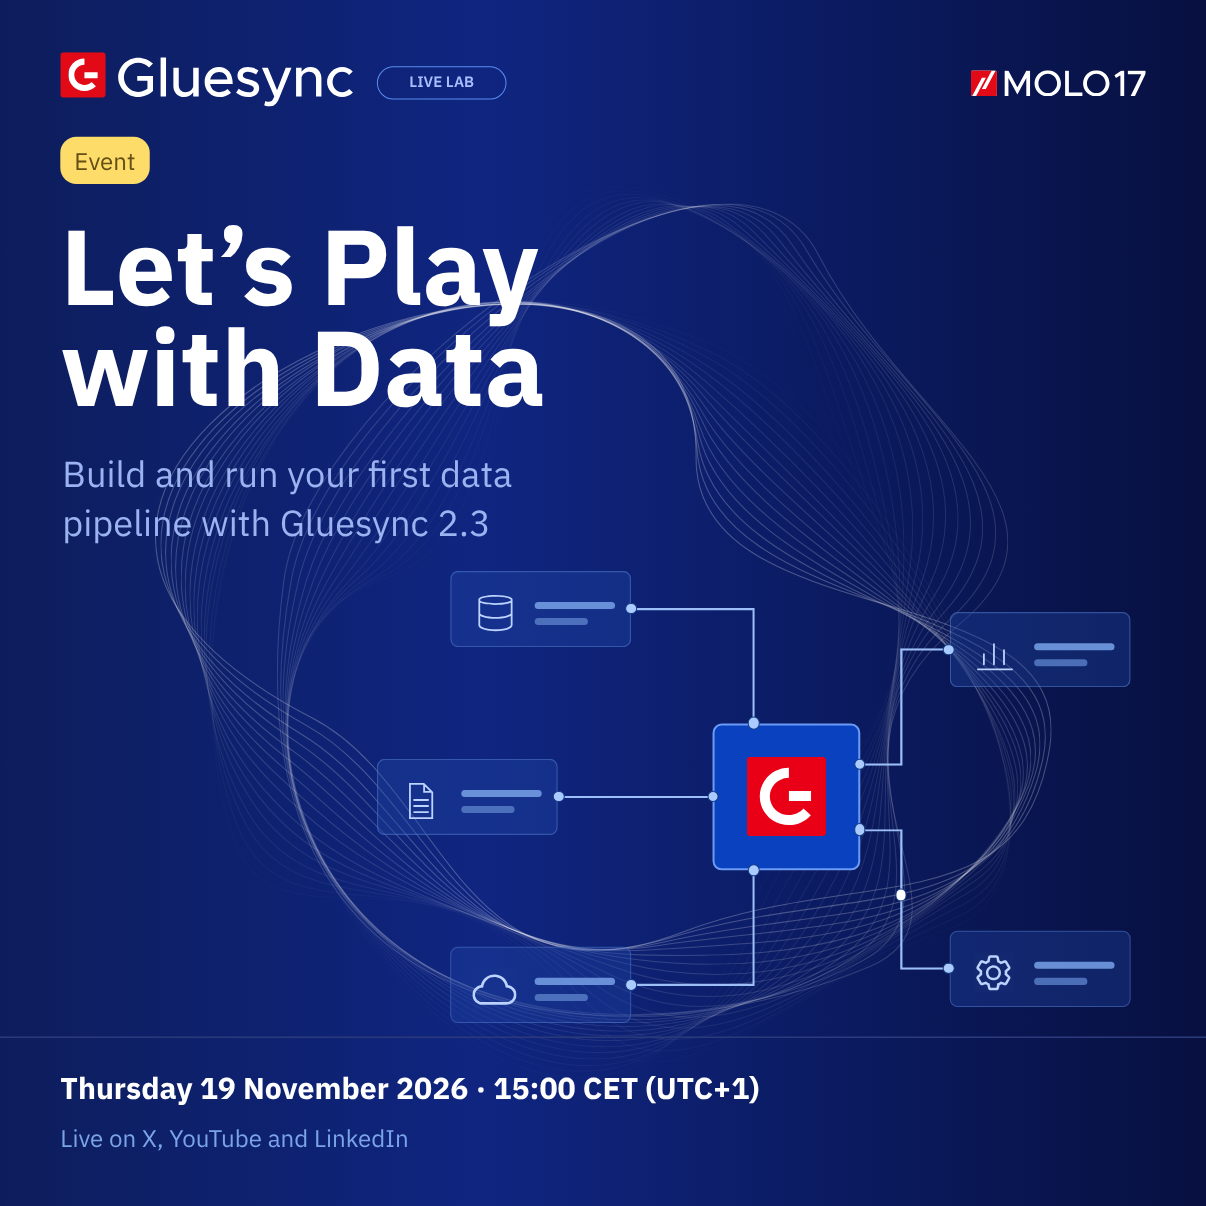
Gluesync Live Lab: Let's Play with Data. Build and run your first data pipeline with Gluesync 2.3, live on X, YouTube and LinkedIn on Thursday 19 November 2026 at 15:00 CET (UTC+1). Free, in English and open to everyone.
Dear data wranglers,
You know the story. The data that runs your business lives on systems built to last: IBM i, Oracle, SQL Server. Everyone else wants it somewhere new, whether that's a cloud data lake, PostgreSQL, Kafka or the analytics team's latest dashboard. And in between sits a nightly batch that everybody prays over and nobody wants to touch.
So we're doing something different. On Thursday 19 November 2026 at 15:00 CET (UTC+1) we're going live on X, YouTube and LinkedIn with the Gluesync Live Lab: Let's Play with Data. Build and run your first data pipeline with Gluesync 2.3. It's free, in English and open to everyone.
Not a webinar. A lab.
No slides. Our engineers start from a blank install and build data integration scenarios with Gluesync 2.3, live: connect a source, capture changes with CDC, map, filter and transform the data, deliver it to a target and keep it running. Every click happens on screen and nothing is pre-baked. If something doesn't go to plan, you'll see how we fix it too. That's what labs are for.
Hands-on demos and live Q&A: ask in the chat, challenge what we build, bring your own scenario.
What's on the workbench
The exact scenarios are still being finalised, and your use cases may shape them. Here's what we plan to cover:
- Connections. Install, open the Control Plane and connect sources and targets: IBM i (AS400) or Oracle on one side, a database, data lake or stream on the other.
- Real-time CDC. Start a snapshot, then watch inserts, updates and deletes flow from source to target as they happen.
- Mapping and filters. Pick the entities, decide how data should land and keep only the rows you need.
- Transformations. No-code field functions for casting, dates and strings, plus custom logic when a dropdown isn't enough.
- Automations and notifications. Schedules, event-driven actions, email and webhook notifications, and Smart Alerts that tell you when a pipeline needs attention.
- Gluesync 2.3 up close. What's new in 2.3, such as the Enterprise brain and the new write-path controls.
Who should tune in
Data engineers and architects who want to judge CDC, mapping and transformations on real sources rather than on a slide. IT managers and heads of data who want to see what it takes to get data out of IBM i, Oracle or SQL Server without rewriting what already works. Gluesync customers planning their 2.3 upgrade. Partners and system integrators looking for scenarios to reuse with their own clients.
Bring your use case
Got a source that won't talk to your target? A batch job you'd love to retire? Tell us when you register. We'll pick a few scenarios to build or discuss live, and if yours needs a deeper look, we'll follow up with a one-to-one session. We never mention your company on air without your permission.
Who's on stage
- Daniele Angeli, Founder & CEO, MOLO17
- Andrea Laspertini, Senior Professional Services Engineer
- Marco Spedicato, Head of QA
Register Now
Registration is free, and everyone who registers gets the recording after the live. Can't make it on the day? Register anyway and the recording comes to you. Tune in for part of it, or all of it. Worst case, you'll watch three of us argue with a nightly batch job, and win.