Real-time data integration platform
One engine. Any source. Any destination.
Gluesync replicates changes across RDBMS, NoSQL, event streaming and data lake environments in real time — with a no-code approach and deployment on your infrastructure.
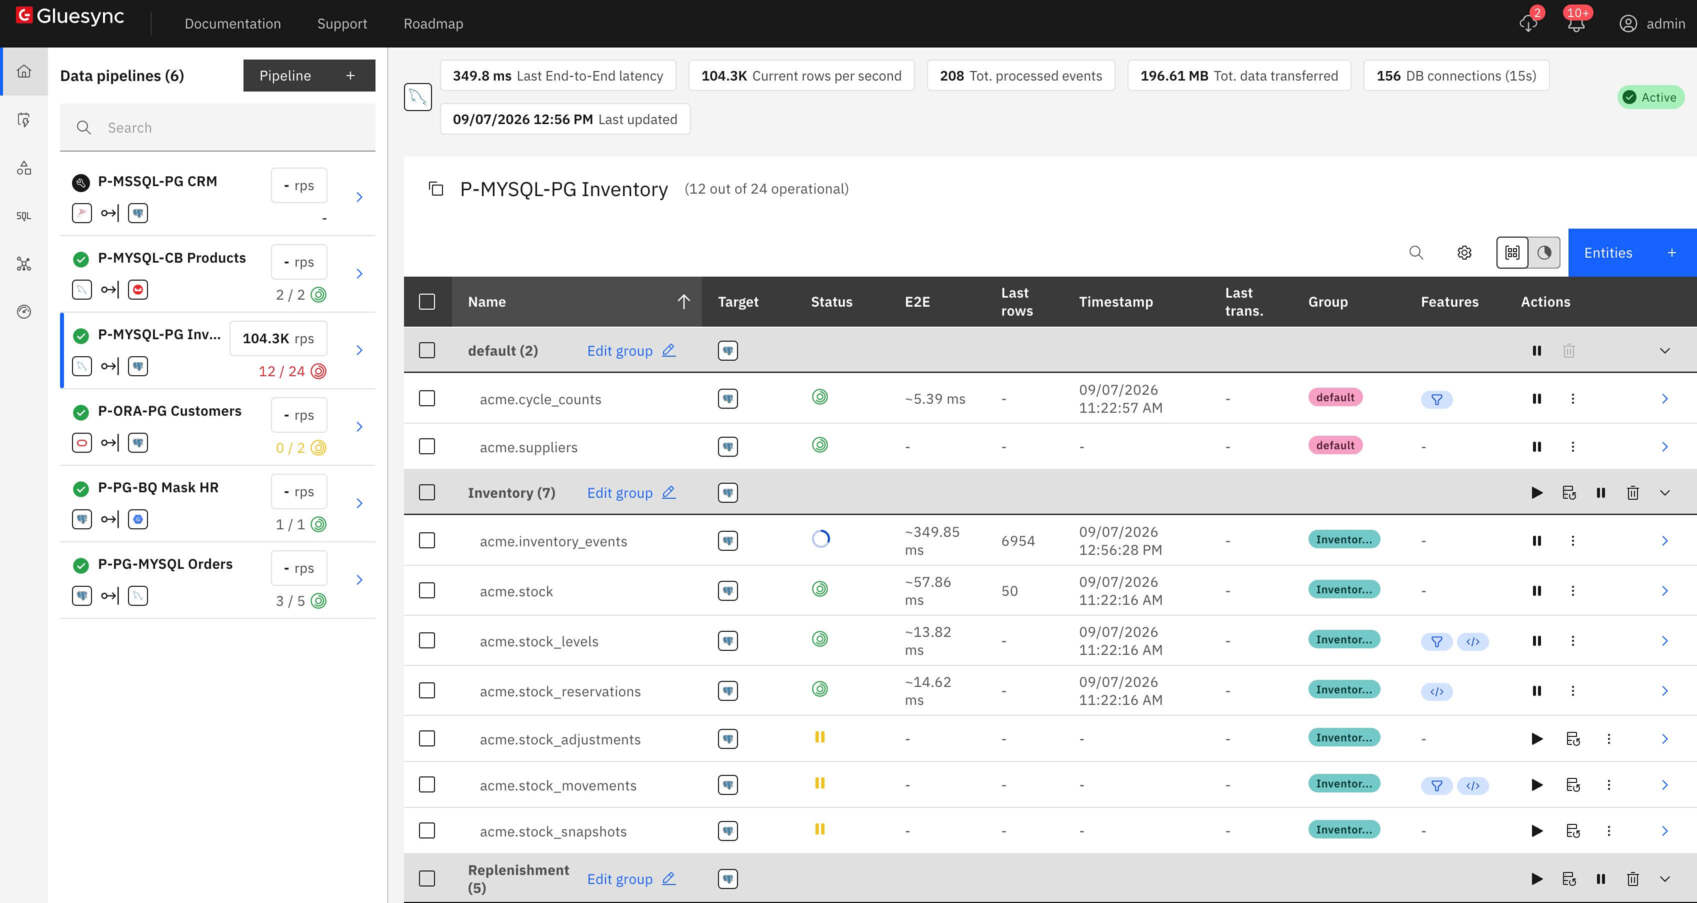
One platform for all use cases.
Integration, knowledge, security and health capabilities — all within the same Web UI.
Trusted by data teams at


The gap to innovation
Don't let data silos hold back your innovation.
Enterprise data lives in silos. Bridging legacy systems and the modern ecosystem with custom code is slow, fragile and expensive.
-
01
Legacy systems hold critical data.
Oracle, IBM i and DB2 remain essential - but data cannot stay trapped inside them.
-
02
Batch pipelines create invisible lag.
Yesterday's data cannot support real-time analytics, AI pipelines and operational decisions.
-
03
Custom integration code becomes fragile.
Every new source, target and schema change adds cost, maintenance and operational risk.
Platform
One platform for all use cases.
Replication is the foundation. Gluesync extends the same architecture across integration, data knowledge, security and data health.


59+
Connectors
<50ms
End-to-end latency
Any
Deployment environment
Zero
Data loss guarantee
Gluesync Platform
One platform. Four capability areas.
From real-time integration to data knowledge, security and system health, Gluesync brings critical data operations into one extensible platform.
Integration
Move, replicate and automate data across heterogeneous environments.
- Replication
- Automations
- Synthetics
Knowledge
Query, understand and improve data across connected systems.
- Querying
- Core Hub MCP
- AI Hub
- Quality
- Discovery
Security
Add operational visibility and controls to help protect the data environment.
- Database vulnerability scans
- Proactive patch alerts
Health
Identify issues early and keep databases and pipelines in good shape.
- Slowness detections
- Remedies application
AI Hub · Available in Gluesync 2.3
The same control plane. A complete agent platform.
Gluesync AI Hub brings your models into the platform—not your data into another AI silo. Build and publish Spark agents, run durable jobs, draft SQL, and call governed tools across 59+ databases while Core Hub policies stay in force.
See the Gluesync AI architecture → Tool calls
list_sql_capable_agents()execute_sql(…) Tool calls
get_pipeline_status(…)get_agent_metrics(…) Tool calls
list_connections()get_connection_usages(…) No compromises
The integration platform that doesn't compromise.
No source overhead. No cloud lock-in. No integration code. Scale as you grow.

No source overhead
Log-based CDC reads the transaction log without polling full tables.
LOG-BASED · ZERO IMPACT

No cloud lock-in
Deploy on your infrastructure. Migrate when you want.
ON-PREMISE · PORTABLE

No integration code
Pre-built connectors, visual mapping and guided setup.
59+ CONNECTORS · NO-CODE

Scale as you grow
Per-core model sized around the needs of each use case.
PER-CORE · LINEAR SCALING
Security by design
Enterprise-grade security. Deployment sovereignty.
- TLS / HTTPS / WSS for every data stream
- AES-256 node-to-node encryption
- No sensitive data persisted within the engine
- Air-gapped, on-premise, private cloud or hybrid
- OIDC identity providers and user realms
- Granular role-based access control
- Full audit logging and traceability
- Kubernetes-native secrets and network policies
Identity & access
Works with the identity providers your teams already use.
Gluesync supports OpenID Connect authentication and is compatible with leading OIDC identity providers, including:



Connectivity
Connect 59+ databases—and more.
Build data flows across relational and NoSQL databases, APIs, file-transfer protocols, cloud storage and event-streaming platforms.
DATABASES
- PostgreSQL
- MongoDB


APIS & ENDPOINTS
- REST API
- HTTP Endpoints


FILE TRANSFER
- FTP
- SFTP


CLOUD STORAGE
- AWS S3
- Azure Data Lake


STREAMING
- Apache Kafka
- Google Pub/Sub


* SELECTED INTEGRATIONS SHOWN. GLUESYNC OFFERS AN EXTENSIBLE API FRAMEWORK FOR CUSTOM CONNECTORS.
Total control
Operational excellence.
Total control over your data pipelines — from orchestration to live monitoring.
- Visual orchestration Manage complexity through one Web UI.
- Programmable logic Refine data with field functions and custom UDFs.
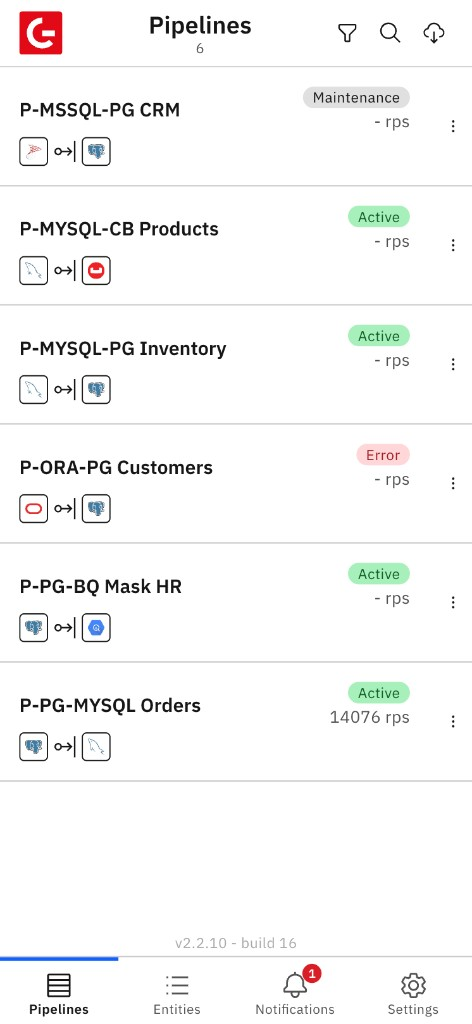
- Live monitoring — also from mobile Track throughput, latency and pipeline health in real time.


Product evolution
A platform that keeps moving.
Follow what is shipping now and what is being built next.
Gluesync Mobile
Your Gluesync operations, wherever you are.
Monitor your Gluesync environment and perform essential operational actions from a mobile experience designed for on-the-go control.
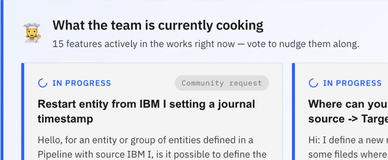
See what the team is building.
Track releases, upcoming capabilities and community requests on the live board.
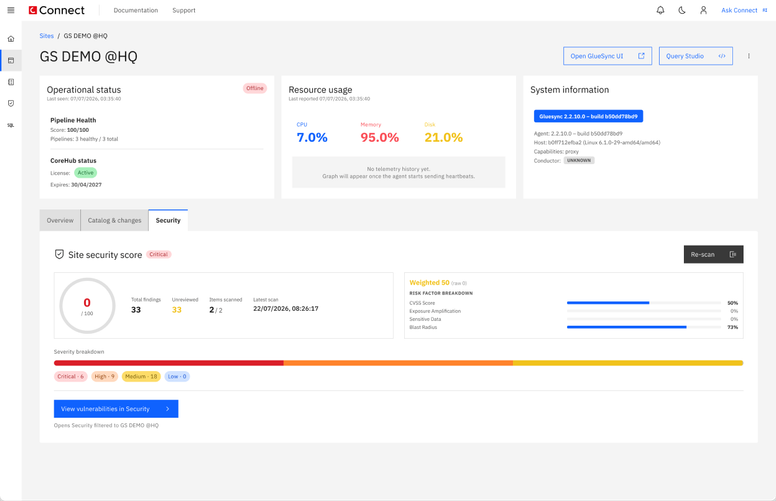
Centralized operational control.
Observe and manage distributed Gluesync sites through a dedicated operational module.
Gluesync provides essential data replication capabilities to Couchbase customers for migrating workloads from legacy relational databases to Couchbase with real-time speed, scalability and flexibility
Matt McDonough SVP Business Development & Strategy, Couchbase

Gluesync is one of the most promising tool i have used for data sync between heterogeneous datastores. Be it relational, non-relational databases or streaming platforms Gluesync empowers data engineering solutions profoundly
Rahul Choubey Engineering Manager at IDFC FIRST Bank
We have assisted many organizations in migrating to RavenDB, often facing data migration challenges. This is where Gluesync has made a significant impact. Besides simplifying data transfer, it also saves time and cuts costs significantly. Through Gluesync, we can deliver value to our customers by simplifying an otherwise complex process
Dejan Milicic Developer Advocate, RavenDB
We see Gluesync as an important component of the Aerospike real-time data platform, allowing customers to bridge either legacy or competitor databases with the fastest NoSQL database in the market, de-risking our customers' journey to Aerospike. This can include migration, as well as the ongoing ability to move and replicate data in real-time
Lenley Hensarling Chief Product Officer at Aerospike, Inc.
FAQ
Frequently asked questions
Technical answers about Gluesync architecture, deployment, connectivity, and documentation.
What is Gluesync?
Gluesync replicates changes across RDBMS, NoSQL, streams, and data lakes in real time — no-code setup, deployed on your infrastructure.
How does Gluesync capture database changes?
Gluesync uses log-based change data capture to read committed changes from transaction logs, journals, or native CDC APIs instead of repeatedly polling full tables.
Where can Gluesync be deployed?
Gluesync runs on your infrastructure and supports on-premises, cloud, private-cloud, and hybrid deployment models.
Can Gluesync connect different kinds of data systems?
Yes. Gluesync builds data flows across relational and NoSQL databases, APIs, file-transfer protocols, cloud storage, and event-streaming platforms.
Where can I find Gluesync technical documentation?
The Gluesync documentation at docs.molo17.com covers architecture, deployment, agents, Core Hub, security, and platform modules.
Ready to bridge your data gap?
Get your 30-day free trial or talk with our data integration specialists.