01 / Fragmented channels
Siloed Data Access
Teams rely on disconnected tools to query different databases, producing inconsistent results and duplicated effort across data access workflows.
Gluesync Platform — Knowledge
Explore, query and assess enterprise data through connected capabilities for data access, quality and discovery.
Why Knowledge Matters
01 / Fragmented channels
Teams rely on disconnected tools to query different databases, producing inconsistent results and duplicated effort across data access workflows.
02 / System overhead
Schema drift, stale metadata, and undocumented transformations erode trust in data quality, making every report a manual verification exercise.
03 / The platform outcome
A unified platform connects querying, quality assessment, and metadata discovery — giving teams a single trusted lens across all connected sources.
Capabilities
Querying, Quality and Discovery work together to explore, validate and map enterprise data — providing full operational intelligence across connected sources.
Multi-source querying
Access and query data across heterogeneous databases through a single unified interface. Query Studio also supplies optional per-session database tools to AI agents through Core Hub MCP under Control Plane RBAC.
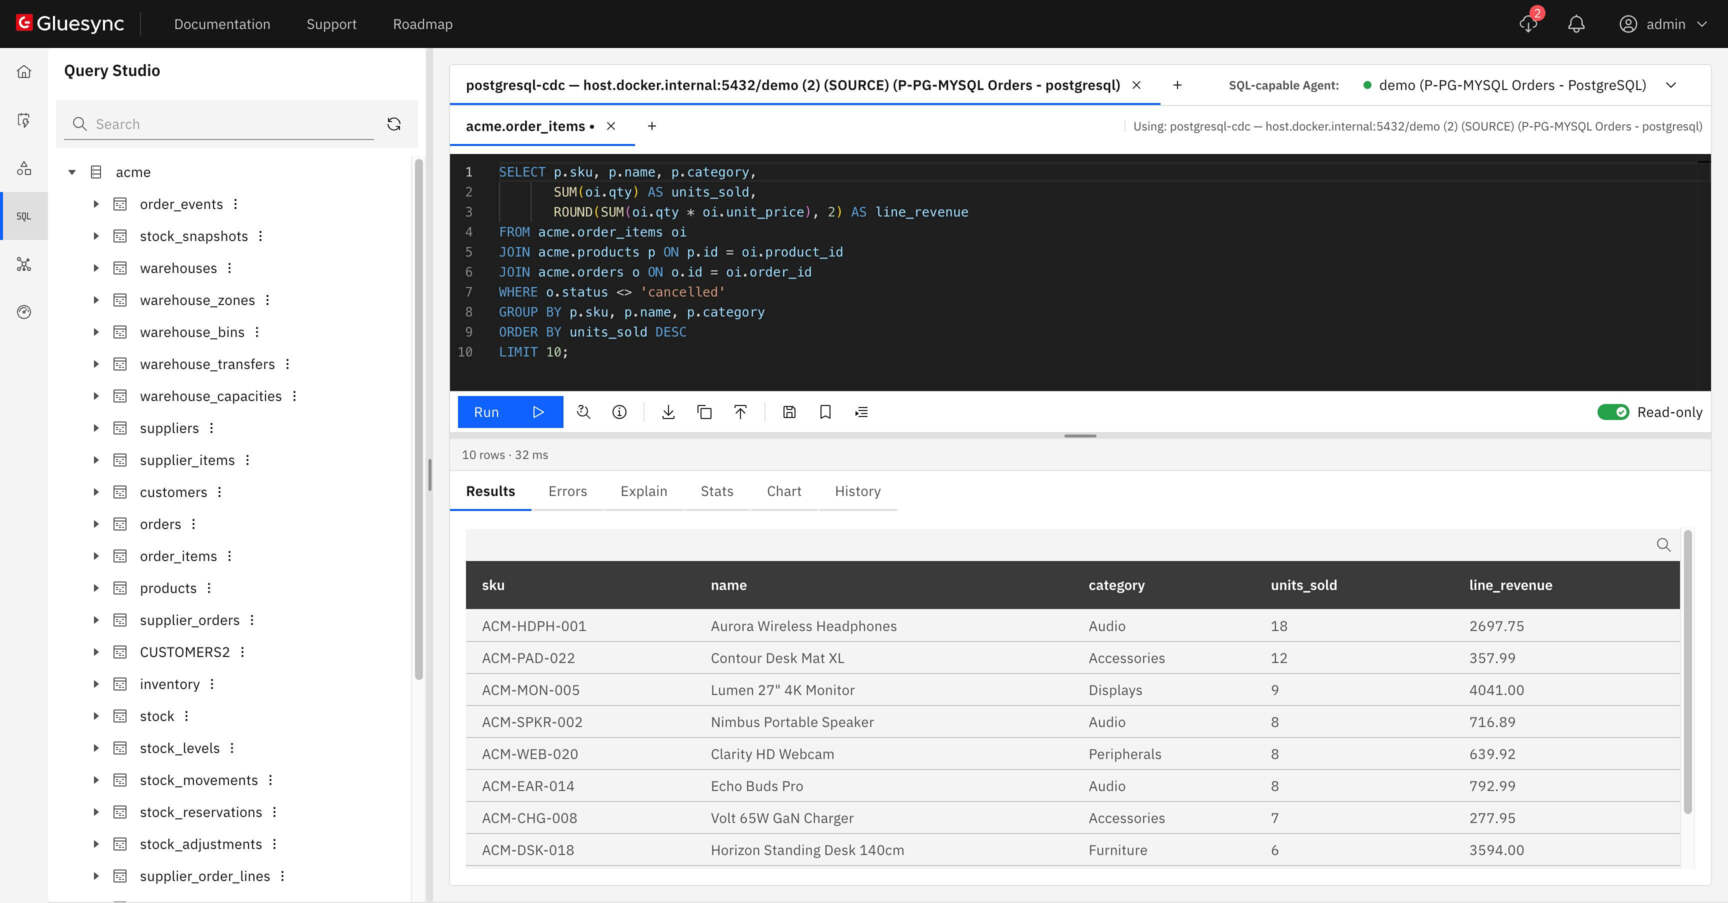
Query across relational, legacy, and NoSQL environments from a single developer workspace. Let Gluesync resolve schemas and fetch results transparently.
Data quality & reconciliation
Ensure data integrity across your pipelines with built-in comparison, coherence validation, and audit capabilities — catching issues before they reach production.
Coming soon
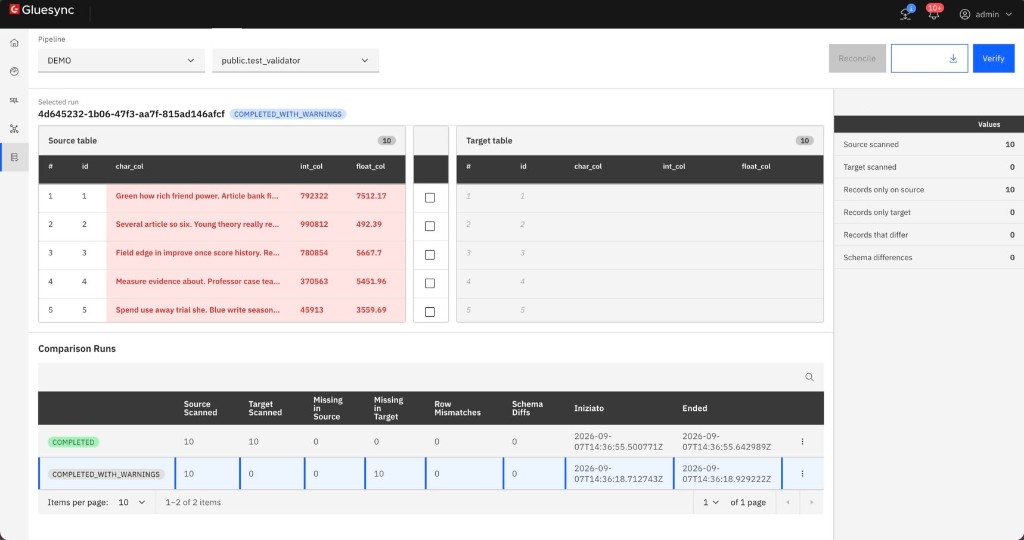
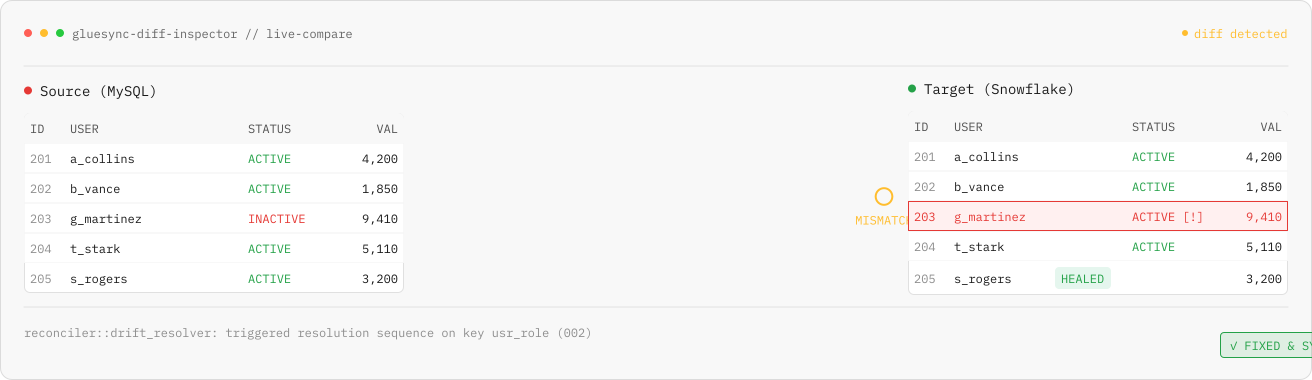
Continuously audits target data mirrors against production source transactions. Instantly flags structural mismatches, schema drifts, and out-of-sync records, applying automated healing policies in real time.
Metadata & lineage
Understand what data exists, how it is structured, and where it flows. Surface metadata relationships, trace lineage across sources, and expose REST APIs directly from your data models.
Coming soon
Map data dependencies visually and monitor schema evolution automatically. Trace any dashboard KPI back to its raw storage elements with continuous column-level pipeline lineage tracking.
Explore the platform
Knowledge works alongside Integration, Security and Health as part of one connected platform.
Current capability area: Knowledge
Inspect schemas, run SQL, and validate live datasets from the Control Plane workbench.
Explore Query Studio →Access and query distributed data sources through a unified layer with Query Forge.
Explore Query Forge →Operate pipelines and SQL from MCP clients under the same Control Plane RBAC as the Web UI.
Explore Core Hub MCP server →Real-time data movement, transformation and synthetic data generation across heterogeneous systems.
Explore Integration →Database security posture assessment, vulnerability scans and proactive patch guidance across connected engines.
Explore Security →Performance monitoring, slowness detection, anomaly alerts and guided remediation for live database workloads.
Explore Health →Resources
Technical guides, API reference, deployment tutorials.
Read documentation ↗What we're building next. Submit feature requests.
View roadmap ↗Access technical support and operational assistance.
Get support ↗Real-time platform availability and incident history.
Check status ↗Explore the Gluesync Platform or discuss your data knowledge strategy with the MOLO17 team.